
Content
# anytype-llm-wiki
<p align="center">
<a href="https://pypi.org/project/anytype-llm-wiki/"><img src="https://img.shields.io/pypi/v/anytype-llm-wiki?color=2b6fb6" alt="PyPI version"></a>
<a href="https://pypi.org/project/anytype-llm-wiki/"><img src="https://img.shields.io/pypi/pyversions/anytype-llm-wiki" alt="Python versions"></a>
<a href="LICENSE"><img src="https://img.shields.io/pypi/l/anytype-llm-wiki" alt="License"></a>
</p>
<p align="center">
<img src="https://raw.githubusercontent.com/Aldeia-IT/anytype-llm-wiki/main/docs/images/hero.jpg" alt="anytype-llm-wiki — a local-first, typed second brain on Anytype" width="100%">
</p>
**A local-first, typed "second brain" on [Anytype](https://anytype.io) — for humans *and* AI agents.**
It takes Andrej Karpathy's *LLM-wiki* idea — let an LLM compile your sources into a curated, interlinked knowledge base you can then query — and builds it on Anytype's native **Objects, Types, and Relations** instead of flat Markdown files. Everything is exposed over the [Model Context Protocol](https://modelcontextprotocol.io), so Claude Code, Cursor, any MCP client — or your own autonomous agents — can both read *and* write it. It runs entirely on your machine.
## Why a typed graph instead of flat notes or plain RAG?
- **Typed Objects and bidirectional Relations — not files.** Knowledge lands as `Entity`, `Concept`, and `Source` objects linked by real, traversable relations in a queryable database. Markdown wikis (Obsidian, Logseq) give you backlinks over text files; Anytype gives you a typed knowledge graph.
- **It detects contradictions.** When newly ingested facts conflict with an already-linked entity, **both positions are kept and cross-linked** (`wiki_contradictions`) and flagged for review — never silently overwritten. Your knowledge base tells you when it disagrees with itself. Flat wikis and vector stores can't.
- **Cited synthesis, not just search.** `wiki_query` returns a prose answer drawn **only from your wiki**, citing the exact Objects it used — and can file the answer back so the wiki gets a little better every time it's used.
- **Local-first.** Anytype + Ollama (embeddings & extraction) + Qdrant (vectors), all on `localhost`. Nothing leaves your machine by default. See [Security & data flow](docs/security-and-data-flow.md).
## Use cases
### 1. A research / knowledge wiki (for you)
Point it at sources — Wikipedia articles, papers, internal docs, your own notes — and it compiles them into typed, interlinked Entities and Concepts *with provenance*, deduping and merging as it goes. Then ask questions in plain language and get answers synthesized **only from your wiki**, each citing the Objects it drew from. It's Karpathy's LLM-wiki pattern on a real database: the graph is browsable in Anytype, and every fact traces back to a Source.
→ Path: `wiki_bootstrap` → `wiki_ingest` → `wiki_query` ([walkthrough](#try-it-in-5-minutes)).
### 2. A secondary brain for an AI agent fleet
Give autonomous agents a **persistent, typed memory that survives sessions** and is shared across projects. Agents narrate what they learn (`wiki_remember`) — decisions, durable facts, and the relations between things — and read it back with citations (`wiki_query`) before starting new work. Consolidation makes repeated writes safe (it dedups, supersedes, and **flags contradictions instead of overwriting**), and a periodic `wiki_lint` surfaces contradictions and staleness for review. One brain, contradiction-aware, that compounds as the fleet works.
→ Path: register as an MCP server in your agent runtime, then `wiki_remember` / `wiki_query`.
> This is exactly how we use it at [Aldeia IT](https://github.com/Aldeia-IT): as the shared long-term memory for our autonomous SDLC agent fleet.
### 3. A research buffer that cuts repeated web search
Researching a topic across many sessions means re-fetching the same facts from the web again and again. Ingest findings once and the wiki becomes a **local, cited cache**: future questions are answered from accumulated knowledge first, with a live web search reserved for genuine gaps — fewer tokens, faster answers, and a provenance trail.
→ Concrete example: a **Capoeira genealogy** research project uses it as exactly this kind of buffer — caching lineage and history research so repeated LLM web-searches are avoided.
## How it works
Everything runs **locally** — no off-machine egress. An MCP client calls the
`anytype-llm-wiki` server, which orchestrates three local backends: **Anytype** (the
typed knowledge graph), **Ollama** (extraction / reasoning LLM + embeddings), and
**Qdrant** (vectors).
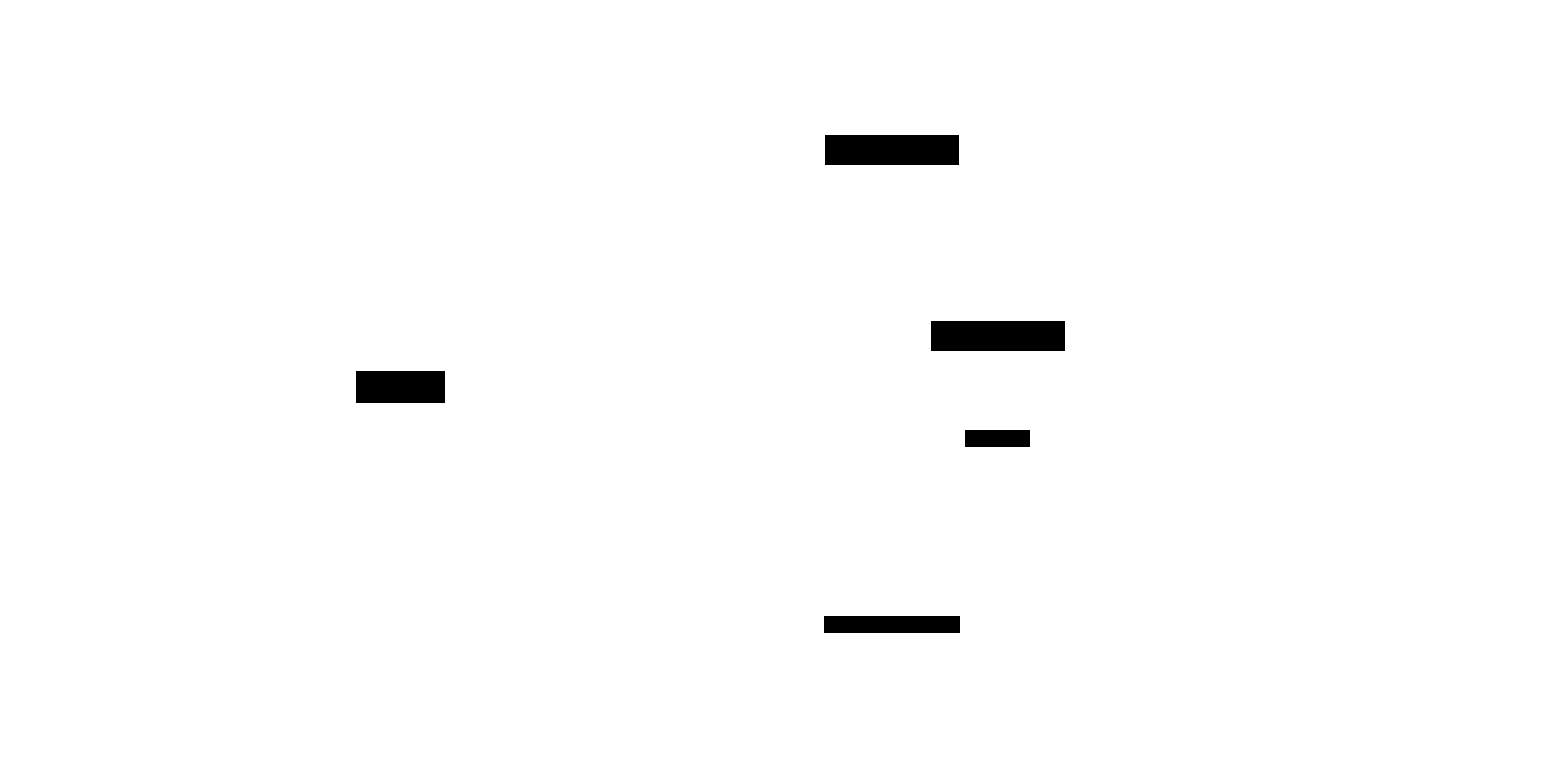
Questions are answered **only from your wiki, with citations** — and the Q&A can be
*filed back* so future questions retrieve from it. The wiki gets more useful the more
you use it:
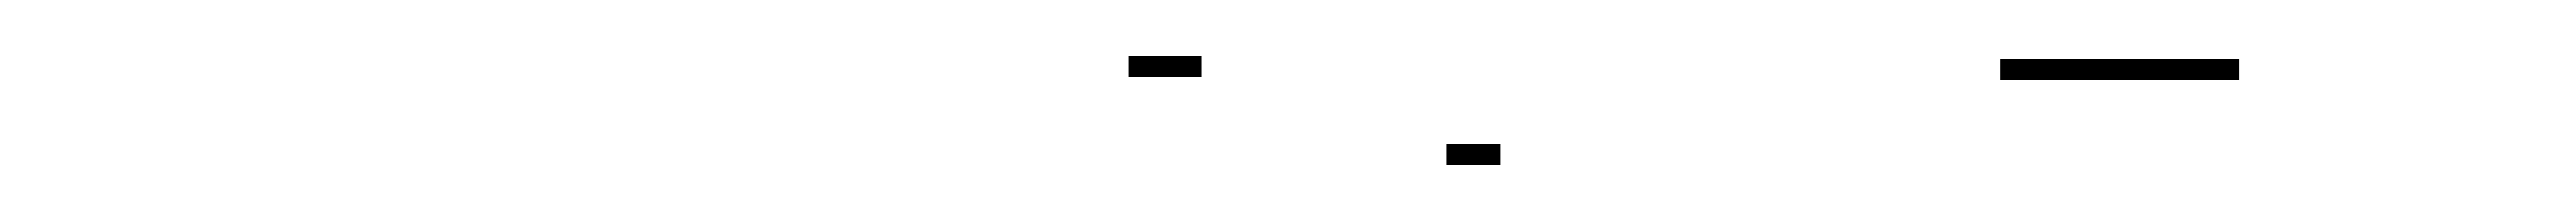
> 📊 **[Full visual guide →](docs/diagrams.md)** — the write pipeline, the typed object
> model, and the self-auditing health check.
Objects carry their knowledge in **properties** (`wiki_facts`, `wiki_definition`, …), not in the object body — so an ingested object shows an empty body in the Anytype client by design; the content is fully indexed and retrievable.
## Quick start
### Prerequisites
- [Anytype](https://anytype.io) desktop (REST API on port 31012)
- [Ollama](https://ollama.ai) with an embedding model: `ollama pull bge-m3` (extraction also uses a small local generation model, e.g. `ollama pull qwen2.5:7b`)
- [Qdrant](https://qdrant.tech): `docker run -p 6333:6333 qdrant/qdrant`
### Install
From [PyPI](https://pypi.org/project/anytype-llm-wiki/) — this puts an `anytype-llm-wiki` command on your PATH:
```bash
uv tool install anytype-llm-wiki # or: pipx install anytype-llm-wiki
```
<details>
<summary>Or run from source (for development)</summary>
```bash
git clone https://github.com/Aldeia-IT/anytype-llm-wiki.git
cd anytype-llm-wiki
uv sync
```
Then prefix the commands below with `uv run` (e.g. `uv run anytype-llm-wiki doctor`).
</details>
Running `anytype-llm-wiki` with **no subcommand** starts the MCP server over stdio.
### Configure
Create a `.env` (only `ANYTYPE_API_KEY` is required):
```bash
ANYTYPE_API_KEY=your-anytype-api-key # Anytype → Settings → API
# Optional (defaults shown):
ANYTYPE_API_URL=http://127.0.0.1:31012
QDRANT_URL=http://127.0.0.1:6333
OLLAMA_URL=http://127.0.0.1:11434
EMBED_MODEL=bge-m3
```
### Verify & provision
```bash
anytype-llm-wiki doctor # read-only preflight (Anytype, Qdrant, Ollama)
anytype-llm-wiki wiki-bootstrap --space-id <id> # idempotently create the typed wiki schema
```
`wiki-bootstrap` is safe to re-run — it reconciles the space to the expected schema without creating duplicates. Re-run it after an upgrade that changes the schema (the CHANGELOG flags those).
### Register as an MCP server
**Claude Code:**
```bash
claude mcp add anytype-llm-wiki -e ANYTYPE_API_KEY=your-key -- anytype-llm-wiki
```
**Claude Desktop / Cursor / other clients** — add to your MCP config:
```json
{
"anytype-llm-wiki": {
"command": "anytype-llm-wiki",
"env": { "ANYTYPE_API_KEY": "your-key" }
}
}
```
> No install? `uvx anytype-llm-wiki` runs the latest from PyPI without installing — use `"command": "uvx", "args": ["anytype-llm-wiki"]` in the JSON config.
### Try it in 5 minutes
**Build a research wiki and query it** (from an empty space):
```bash
# 1. Provision the typed schema.
anytype-llm-wiki wiki-bootstrap --space-id <id>
# 2. Compile a source into typed, interlinked Objects (auto-reindexes).
anytype-llm-wiki wiki-ingest --space-id <id> \
--source https://en.wikipedia.org/wiki/Retrieval-augmented_generation
# 3. Ask a question — answered only from your wiki, with citations.
# --file-back stores the Q&A so it can be retrieved by FUTURE queries.
anytype-llm-wiki wiki-query --space-id <id> \
--question "What is retrieval-augmented generation?" --file-back
```
**Give an agent memory** — once registered over MCP, your agent can:
```
wiki_remember(space_id, "Qdrant 1.12 added native multi-tenancy via payload partitioning.", subject_hint="Qdrant")
wiki_query(space_id, "What do we know about Qdrant multi-tenancy?")
```
## The MCP tools
| Tool | What it does |
|------|--------------|
| `semantic_search` | Search the vault by meaning. `query`, `space_id?`, `types?`, `ingested_after?`, `ingested_before?`, `source_type?`, `domain_tags?`, `limit?` (default results exclude `wiki_source` excerpts unless `types=["wiki_source"]` or `source_type` is given) |
| `reindex_anytype` | Trigger an incremental reindex. `space_id?` |
| `wiki_bootstrap` | Provision the typed wiki schema in a space. `space_id`, `domain_tags?` |
| `wiki_ingest` | Compile a source (URL or file) into curated, interlinked Objects with provenance; auto-reindex. `source`, `space_id`, `domain_hint?` |
| `wiki_remember` | Consolidate an agent's natural-language narration into typed Objects (LLM merge/dedup/conflict-flag). Fleet-safe **queue-submit**: concurrent writers never block or lose writes (no read-after-write). `space_id`, `knowledge`, `subject_hint?`, `kind?`, `relations?`, `domain_tags?`, `source?` |
| `wiki_query` | Query the wiki for a synthesized, source-cited answer (tiered retrieval + local synthesis); optionally file the answer back. `question`, `space_id`, `file_back?`, `types?`, `ingested_after?`, `ingested_before?`, `source_type?` (no-op — accepted for API symmetry), `domain_tags?` |
| `wiki_lint` | Read-only structural health check (contradictions, orphans, staleness, asymmetric relations, …), ranked by severity. `space_id`, `severity_threshold?`, `include_duplicates?` |
Extraction and synthesis run on local Ollama by default (`WIKI_EXTRACT_MODEL`, default `qwen2.5:7b`); pointing `WIKI_EXTRACT_ENDPOINT` at a hosted API moves that processing off-machine behind a one-time consent gate — see [Security & data flow](docs/security-and-data-flow.md).
## Key behaviors worth knowing
- **Contradiction detection is automatic, but scoped.** At ingest, when an updated **Entity or Concept**'s new facts/definition conflict with an already-linked peer, both are cross-linked via `wiki_contradictions` and left for review. Detection is bounded to **already-linked peers** — an Object that contradicts something it isn't linked to won't surface a finding yet. Both **entity** and **concept** contradictions are now flagged by `wiki_lint` (severity `critical`) and are resolved by setting `wiki_last_reviewed` on the Object. They are also recorded in `wiki_contradictions` and browsable in Anytype. Don't over-trust a clean contradiction column.
- **Cited synthesis + a compounding loop.** `wiki_query` answers only from retrieved Objects and cites them in `sources_consulted` — including the 1-hop linked neighbours that actually fed the answer, not only the top-k seeds, so the citation list honestly reflects every Object the answer drew from (neighbour fan-out is bounded by `WIKI_QUERY_MAX_NEIGHBORS`, default 16, and deterministically ordered). File-back still records only the seed Objects, so `wiki_drew_from` stays seed-scoped. A clean answer that meets the file-back gate (≥ 3 cited sources **and** ≥ 100 words, or `file_back=True`) is stored as a typed Query Object; after the next reindex it becomes retrievable itself — so the wiki improves with use. Treat citation titles and deeplinks as untrusted data — surface them, but don't auto-follow a deeplink as trusted. (Filed answers surface only after that reindex — see [known limitations](docs/known-limitations.md).)
- **Safe repeated writes (`wiki_remember`).** Reworded duplicates merge, genuinely new facts append, superseding facts replace (the prior text is recorded in the WikiLog and recoverable), contradictions are flagged not overwritten, and re-asserting the same knowledge converges to a no-op.
- **Fleet-safe concurrent writes (no read-after-write).** Independent agents on separate PIDs/terminals can `wiki_remember` the *same* space at once: each durably queues its subjects (a lock-free append to the work-log) and whichever process holds the per-space lock drains them — nobody blocks, nobody's learnings are dropped. A submit may return *before* its subjects are applied, so a `wiki_query` immediately afterward may not see them yet (the wiki is for the *next* agent, not the submitter's own next line). Same-host only — see [known limitations](docs/known-limitations.md). The `wiki-drain` CLI forces a synchronous drain when you need one.
- **Tiered retrieval.** Below `WIKI_INDEX_THRESHOLD` (default 200) Objects, `wiki_query` reads the whole wiki directly (exhaustive and fast); above it, it uses vector search plus 1-hop neighborhood expansion.
- **Incremental, schedulable indexing.** Only changed objects are re-embedded. For continuous indexing, run `reindex_anytype` on a schedule (cron/launchd — a sample launchd plist ships at [`docs/samples/com.aldeia.anytype-llm-wiki-reindex.plist`](docs/samples/com.aldeia.anytype-llm-wiki-reindex.plist)). For high agent write-rates, set `WIKI_AUTO_REINDEX=false` and batch a scheduled reindex, since reindex cost scales with total space size.
## Performance
Benchmarked on a Mac Mini (Apple Silicon):
| Operation | Time |
|-----------|------|
| Single search query | **0.22s** |
| Index 50 chunks | 0.73s |
| Full reindex (500 chunks) | ~7s |
## Configuration
`ANYTYPE_API_KEY` is the only required variable; sensible defaults cover the rest.
| Variable | Default | Description |
|----------|---------|-------------|
| `ANYTYPE_API_URL` | `http://127.0.0.1:31012` | Anytype REST API endpoint |
| `QDRANT_URL` | `http://127.0.0.1:6333` | Qdrant endpoint |
| `OLLAMA_URL` | `http://127.0.0.1:11434` | Ollama endpoint |
| `EMBED_MODEL` / `EMBED_DIMS` | `bge-m3` / `1024` | Embedding model and its vector dimensions (must match) |
| `WIKI_EXTRACT_MODEL` | `qwen2.5:7b` | Local model for extraction / synthesis / consolidation |
| `WIKI_ALIAS_ADJUDICATION` | `off` | **⚠️ EXPERIMENTAL — enable at your own risk.** LLM alias-merge in entity resolution (Step 3). Off by default. Only runs on a vetted model; **enabling it on an unvetted model makes the MCP server refuse to start** (loud `[CONFIG ERROR]`). See the warning below. |
| `WIKI_ALIAS_VETTED_MODELS` | _(empty)_ | Comma-separated extra extraction-model **prefixes** trusted for alias adjudication, unioned with the built-in `qwen3.5-mlx`. Adding your model here is the override (there is no force flag). |
> **⚠️ `WIKI_ALIAS_ADJUDICATION` is experimental — leave it off unless you accept the risk.**
> *What it does:* on a write, when exact- and fuzzy-title matching don't find an existing object, it asks a local LLM whether the new entity is the **same real-world entity** as a lexically-similar existing one (an alias / abbreviation / rename) and, if so, **merges** into it instead of creating a duplicate — automatically catching dupes like `k8s` → `Kubernetes`.
> *The risk:* the judgment is **destructive and irreversible-ish** (the new object is never created), and even a vetted model **over-merges distinct entities** on real, messy data (observed ~7–10% on a real graph — e.g. merging a person into the eponymous project, a testnet into its mainnet, or a collection into one of its members). It is deliberately conservative and gated behind this off-by-default flag + a vetted-model startup check, but **it can still corrupt your graph**. For curation we recommend the **non-destructive** path instead: `wiki_lint --include-duplicates`, which only *surfaces* `potential_duplicate` suggestions for a human to review and merge.
| `WIKI_EXTRACT_ENDPOINT` | *(unset → local Ollama)* | Hosted LLM endpoint for extraction (off-machine; consent-gated) |
| `WIKI_INDEX_THRESHOLD` | `200` | Object count at which `wiki_query` flips Tier 1 → Tier 2 |
| `WIKI_QUERY_MAX_NEIGHBORS` | `16` | Cap on distinct 1-hop neighbours `wiki_query` fans out to fetch and cite per query |
| `WIKI_AUTO_REINDEX` | `true` | Auto-reindex after each write (set `false` to batch via a scheduled reindex) |
| `WIKI_LOCK_DIR` / `WIKI_WORKLOG_DIR` | `~/.local/share/anytype-llm-wiki/{locks,worklog}` | Host-local lock + durable subject work-log. A same-host agent fleet writing one shared vault **must share both** (see [known limitations §10](docs/known-limitations.md)); the work-log holds narrated content transiently — treat as sensitive ([data flow](docs/security-and-data-flow.md)) |
Additional `WIKI_SYNTH_*` and `WIKI_LINT_*` tuning knobs exist with sensible defaults — you won't normally need them.
## Architecture
- **Anytype client** — reads/writes objects via the REST API; handles pagination and auth.
- **Chunker** — splits markdown by headings, falls back to paragraphs; each chunk carries object/space/type/heading metadata.
- **Embedder / Indexer** — Ollama `/api/embed`; incremental by `last_modified_date`, re-embedding only changed objects and cleaning up vectors for deleted ones.
- **Wiki pipeline** — LLM extraction → entity/concept resolution → typed Objects with bidirectional Relations → contradiction detection → cited synthesis.
- **MCP server** — [FastMCP](https://github.com/jlowin/fastmcp) over stdio, exposing the seven tools above.
- **doctor** — read-only preflight (Anytype, Qdrant, Ollama, embedding model).
📊 **[Architecture — Visual Guide](docs/diagrams.md)** — diagrams of the components, the write/read pipelines, the typed object model, and the health check.
For the internals — the write pipeline, how consolidation corrects reality, entity-resolution & duplicate handling, the concurrency model, and the no-drop subject work-log — see [**Architecture & internals**](docs/architecture.md).
## Supply-chain posture
Dependencies are pinned in two layers: **`uv.lock`** locks every direct and transitive dependency to an exact, content-hashed version (CI runs `uv lock --check`), and **`pyproject.toml`** declares compatible ranges with next-major upper bounds so a transitive resolution can't silently cross a major version. Release artifacts are built cache-free and signed with a [SLSA build-provenance attestation](https://docs.github.com/actions/security-guides/using-artifact-attestations); once wheels are published you'll be able to `gh attestation verify` them against this repo.
## Roadmap
- Hybrid search — metadata filtering (object type + date range) ships now; keyword/sparse fusion remains roadmap (#327); tag/source filtering tracked in #336
- Contradiction detection beyond linked peers (semantic pre-filter)
- Cross-space federation with access control
- Webhook-based indexing when Anytype adds webhook support
See the [GitHub Releases](https://github.com/Aldeia-IT/anytype-llm-wiki/releases) and [CHANGELOG](CHANGELOG.md) for what's shipped.
## Comparison
| | anytype-llm-wiki | Flat-file wiki (Obsidian / Logseq) | Plain vector RAG |
|--|------------------|-----------------------------------|------------------|
| Storage | Typed Anytype Objects + Relations | Markdown files + backlinks | Chunks in a vector DB |
| Knowledge model | Entities/Concepts in a queryable graph | Documents you organize by hand | Opaque chunks |
| Contradiction handling | **Detected & cross-linked for review** | None | None |
| Answers | **Synthesized, with Object citations** | You read & connect | Retrieved snippets |
| Agent read **and** write | **Yes (MCP)** | Manual | Read-mostly |
| Local-first | Yes (Ollama + Qdrant) | Yes | Varies |
It also differs from API-access MCPs like [`anyproto/anytype-mcp`](https://github.com/anyproto/anytype-mcp) (object CRUD, no semantic/vector search) and [`wethegreenpeople/anytype-mcp`](https://github.com/wethegreenpeople/anytype-mcp) (ChromaDB, full re-embed on start): embedding-backed semantic retrieval **plus** the typed-wiki pipeline is the core differentiator.
## Contributing
Maintained by [Aldeia IT](https://github.com/Aldeia-IT) for our own use and published openly. We're **not actively soliciting contributions right now** and may be slow to respond to issues and PRs — but you're welcome to fork it. **Security issues:** please use [private reporting](SECURITY.md), not a public issue. Dev setup and expectations are in [CONTRIBUTING.md](CONTRIBUTING.md); please be kind ([Code of Conduct](CODE_OF_CONDUCT.md)).
## License
MIT. See [CONTRIBUTING.md](CONTRIBUTING.md) for contribution licensing (inbound = outbound).
## Trademarks
Anytype is a trademark of Any Association. This project is not affiliated with, sponsored by, or endorsed by Any Association or the Anytype project; the name is used solely to identify the platform this software integrates with.
MCP Config
Below is the configuration for this MCP Server. You can copy it directly to Cursor or other MCP clients.
mcp.json
Connection Info
You Might Also Like
No recommendations available