

Content
# Cortex Protocol
🧠 **One memory. Every agent.** — user-owned, cross-agent AI memory over the Model Context Protocol.
[](https://pypi.org/project/cortex-protocol/)
[](https://pypi.org/project/cortex-protocol/)
[](https://pypi.org/project/cortex-protocol/)
[](https://github.com/fernsdavid25/cortex-protocol/blob/main/LICENSE)
[](https://github.com/fernsdavid25/cortex-protocol/actions/workflows/ci.yml)
[](https://codecov.io/gh/fernsdavid25/cortex-protocol)
**Works with Claude Code · Cursor · Claude Desktop · VS Code**
You own **one** portable memory, and any AI agent connects to it over MCP with your consent.
Self-host it as a local stdio server — a single SQLite file, your own Gemini key (BYOK), **nothing
phones home** — and `recall` does **no** server-side LLM generation, so the only runtime cost is your
own embedding tokens.
> **📊 0.932 LongMemEval_S · 0.813 LoCoMo** — the only memory system publishing $/question, and the
> only one at 0.9+ on LongMemEval_S with a cost-efficient-tier reader: a **Gemini Flash reader** at
> **~$0.0396/question** on LongMemEval_S and **~$0.0034/question** on LoCoMo.† Raw standing: **#2**
> on LongMemEval_S (behind Mastra 0.949), **#3** on LoCoMo. Judge disclosure in [Results](#results).
<sub>† Per-question cost is computed from measured token counts at Google's **confirmed list
prices** (paid tier) for the reader model.</sub>
## Quickstart — self-host (local memory in your agent)
The local server (`cortex-mcp`) is a **stdio MCP server**: your own Gemini key (BYOK), memories in a
local SQLite file (`~/.cortex/memory.db`), **nothing phones home**.
1. **Get a Gemini key** (free): <https://aistudio.google.com/apikey>
2. **Add Cortex to your MCP client.** Every client uses the same `mcpServers` shape — only the file
differs:
```json
{
"mcpServers": {
"cortex": {
"command": "uvx",
"args": ["--from", "cortex-protocol", "cortex-mcp"],
"env": { "GEMINI_API_KEY": "your-key-here" }
}
}
}
```
| Client | Config file |
|---|---|
| **Claude Code** | `~/.claude.json` (global), or `.mcp.json` in a project |
| **Cursor** | `~/.cursor/mcp.json` (global), or `.cursor/mcp.json` in a project |
| **Claude Desktop** | `claude_desktop_config.json` (Settings → Developer → Edit Config) |
| **VS Code** | `.vscode/mcp.json` |
Restart the client. That exposes six tools (the last two are gated on opt-in memory layers — see
**Config (env)** below):
| Tool | What it does |
|---|---|
| `memorize(content, kind?, tags?)` | Save a durable memory (optionally classified into one of six kinds). |
| `recall(query, limit?)` | Retrieve the most relevant memories (hybrid dense + BM25, RRF; no LLM generation). |
| `list_memories(limit?)` | List the most recent memories. |
| `forget(memory_id)` | Delete a memory (a short id prefix works if unambiguous). |
| `recall_about(entity, limit?)` | Exhaustive dossier for one entity — a person, place, project, org, thing, or yourself — every relationship plus every memory attached to it. A pure keyed read, no LLM/embedding call. **Requires `CORTEX_GRAPH=1`.** |
| `recall_timeline(since?, until?, limit?)` | Dated event timeline — memories ordered by their extracted `event_time` (for "what happened when" questions), optionally bounded by ISO dates. A pure keyed read, no LLM/embedding call. **Requires `CORTEX_EPISODIC=1`.** |
**From a checkout** (to run your own working copy instead of the published package):
`python -m cortex.mcp.server`, or in the client config use
`"command": "uv", "args": ["run", "--with", "fastmcp", "python", "-m", "cortex.mcp.server"]`.
Note the `--from cortex-protocol` in the config above — a bare `uvx cortex-mcp` resolves to an
unrelated package.
**Config (env):** `GEMINI_API_KEY` / `GOOGLE_API_KEY` (required); optional `CORTEX_DB_PATH`,
`CORTEX_USER_ID`, `CORTEX_EMBED_MODEL`, `CORTEX_EMBED_DIM`, `CORTEX_TOP_K` (default recall depth 5).
**Opt-in memory layers (off by default).** `CORTEX_GRAPH=1` builds the entity graph and enables
`recall_about`; `CORTEX_EPISODIC=1` structures event time / actor / location and enables
`recall_timeline`; `CORTEX_EXTRACT_MODEL` (default `gemini-2.5-flash-lite`) is the model that does
that extraction. Enabling either adds **one cheap flash-lite call per `memorize`** (write-time only,
on your own key — when both are on they share a single extraction call). **`recall` stays
byte-identical**, so the published recall cost is unchanged. See
[`examples/`](https://github.com/fernsdavid25/cortex-protocol/tree/main/examples) and
[`.env.example`](https://github.com/fernsdavid25/cortex-protocol/blob/main/.env.example).
**Claude Desktop one-click:** build the `.mcpb` bundle and drag it onto Desktop — it prompts for your
Gemini key and runs the same six tools. See
[`packaging/mcpb/`](https://github.com/fernsdavid25/cortex-protocol/tree/main/packaging/mcpb).
## Why Cortex
- **User-owned, not company-owned.** *You* decide which agents see your memory — versus incumbents
where the business owns it. One memory, every agent.
- **The cost is published.** ~$0.0396/question on LongMemEval_S, ~$0.0034 on LoCoMo† — measured
token counts at Google's confirmed list prices. No other memory system publishes a $/question at
all, so there is nothing to compare it against yet. It targets accuracy *per dollar*, not raw
accuracy at any cost.
- **Run anywhere, no operator cost.** Self-host is a single SQLite file — no Docker, no DB server.
One config snippet wires it into any MCP client.
## Results
**📊 0.932 LongMemEval_S · 0.813 LoCoMo.** Two public long-term-memory benchmarks, with the
standing stated plainly: raw **#2** on LongMemEval_S (behind Mastra 0.949) and raw **#3** on
LoCoMo. What is distinct is the cost side — Cortex is the only memory system publishing
$/question, and the only one at 0.9+ on LongMemEval_S with a cost-efficient-tier reader. No
competitor's $/question has been measured, by us or by them, so no cost comparison is claimed.
| Benchmark | Cortex | Raw rank | Reader (cost†) | Recall@k (session-level‡) |
|---|---|---|---|---|
| **LongMemEval_S** (500 q) | **0.932** | #2 raw | `gemini-3.5-flash`, top_k=50, preference-mode, answer-first · **~$0.0396/q** | 0.998 |
| **LoCoMo** (1986 q) | **0.813** | #3 raw | `gemini-2.5-flash`, top_k=100, answer-first · **~$0.0034/q** | 0.998 |
<sub>† $/q is computed from measured token counts (25,723.5 in / 113.5 out per question on
LongMemEval_S; 10,468.4 in / 92.9 out on LoCoMo) at Google's **confirmed list prices** for the
reader model — `gemini-3.5-flash` at $1.50/$9.00 per 1M input/output tokens, `gemini-2.5-flash` at
$0.30/$2.50 (see `bench/cortex_bench/metrics.py`).</sub>
> **‡ Read this recall number the narrow way.** It is **session-level**: it scores a hit when the
> retrieved set contains the *session* holding the gold evidence. On LongMemEval that is the
> dataset's own gold granularity, so 0.998 is measured against exactly what the benchmark defines.
> On LoCoMo the dataset ships **turn-level** evidence (`"D1:3"` = session 1, turn 3), so
> session-level recall answers the easier question there. Measured turn-level full-evidence
> coverage on LoCoMo is **0.915 at k=100** and **0.639 at k=8** — read 0.998 as "we surfaced the
> right conversation", not "we surfaced the right memory".
>
> The stricter metric now ships: `coverage_at_k` in
> [`metrics.py`](https://github.com/fernsdavid25/cortex-protocol/blob/main/bench/cortex_bench/metrics.py)
> scores retrieval against individual gold **turns**, joined on LoCoMo's own `dia_id`. Four
> evidence fields in the released corpus pack several ids into one string
> (`"D22:1 D22:2 D9:10 D9:11"`); matching the raw field keeps only the first and silently shrinks
> the gold set, so the parser tokenizes first — worth 13 recovered gold turns across the corpus.
#### The reader frontier — buy accuracy with dollars, not with a different memory system
The same retrieval, the same 500 questions, the same prompt — only the reader model changes. This
is the trade the memory layer exposes, priced:
| Reader (LongMemEval_S, n=500) | Accuracy | $/question | Cost per **correct** answer |
|---|:--:|:--:|:--:|
| `gemini-2.5-flash` | 0.848 | **$0.0079** | $0.0093 |
| `gemini-3.5-flash` | **0.932** | $0.0396 | $0.0425 |
**+8.4 accuracy points for ~5× the reader cost, with the memory system held fixed.** Retrieval is
byte-identical across the two arms — same index, same top-k, same fused ranking — so the delta is
reader capability, not retrieval. Pick your point on that curve with `CORTEX_READER_MODEL`;
nothing else changes.
### How Cortex compares (LongMemEval_S)
| System | LongMemEval_S | Reader | ~$/q | Judge |
|---|---|---|---|---|
| **Cortex** (this repo) | **0.932** | `gemini-3.5-flash` (cost-efficient tier) | **~$0.0396** | gemini-flash |
| Mastra | 0.949 | `gpt-5-mini` (premium) | — | GPT-4o |
| Zep / Graphiti | 0.712 | `gpt-4o` (premium) | — | GPT-4o |
| Mem0 | not published¹ | — (graph) | — | — |
<sub>Numbers from the verified [leaderboard research](https://github.com/fernsdavid25/cortex-protocol/blob/main/bench/results/leaderboard_research.md).
**Not apples-to-apples:** competitor scores are self-reported under *their own* judges; Cortex is
graded by a `gemini-3.5-flash` judge (likely more lenient than the canonical `gpt-4o-2024-08-06`), and
`~$/q` is only published where Cortex measures it — no competitor `$/q` has been measured. ¹Mem0 has
no verifiable LongMemEval_S number that survived verification — it reports LoCoMo (0.61–0.66)
instead. The `~$0.0396` figure is Cortex's own measured token counts priced at Google's confirmed
`gemini-3.5-flash` list prices.</sub>
> **Judge disclosure (load-bearing).** All Cortex numbers above are graded by an **LLM judge =
> `gemini-3.5-flash`**. The canonical LongMemEval judge is `gpt-4o-2024-08-06`; a Gemini judge is
> likely *more lenient*, so a GPT-4o re-grade (pending an OpenAI key) may lower these. The headline
> run also used the **same model family as both reader and judge**, so a self-preference bias cannot
> be excluded and a cross-family re-grade is planned. As one cross-model sanity check, an independent
> Claude panel re-graded all 282 LoCoMo multi-hop cases and closely tracked the harness (panel 0.528
> vs harness 0.589). The published **$/question** is measured from token counts at Google's
> confirmed list prices and does not depend on the judge.
**LongMemEval_S 0.932** — per question type: single-session-user 0.957, single-session-assistant
0.982, single-session-preference 0.900, knowledge-update 0.949, temporal-reasoning 0.925,
multi-session 0.902, abstention 0.867 (mean ~25.7k input tokens/q). Under our judge, 0.932 sits
**above ByteRover (0.928, claimed) and Hindsight (0.914)** and below only the premium-reader leader
**Mastra (0.949, gpt-5-mini)** — while clearing Emergence (0.860), Supermemory (0.852), and Zep
(0.712), all of which use pricier readers. *(Competitor rows use their own judges — the leaderboard
is not apples-to-apples; canonical judge is GPT-4o.)*
#### Per question type — Cortex vs the field
One overall number hides where a memory system wins or loses. Split by LongMemEval_S question
type, Cortex — the **only cost-efficient-tier-reader system in the field** — stays in the top tier
of the premium-reader systems, and leads outright on single-session-assistant and multi-session
recall:
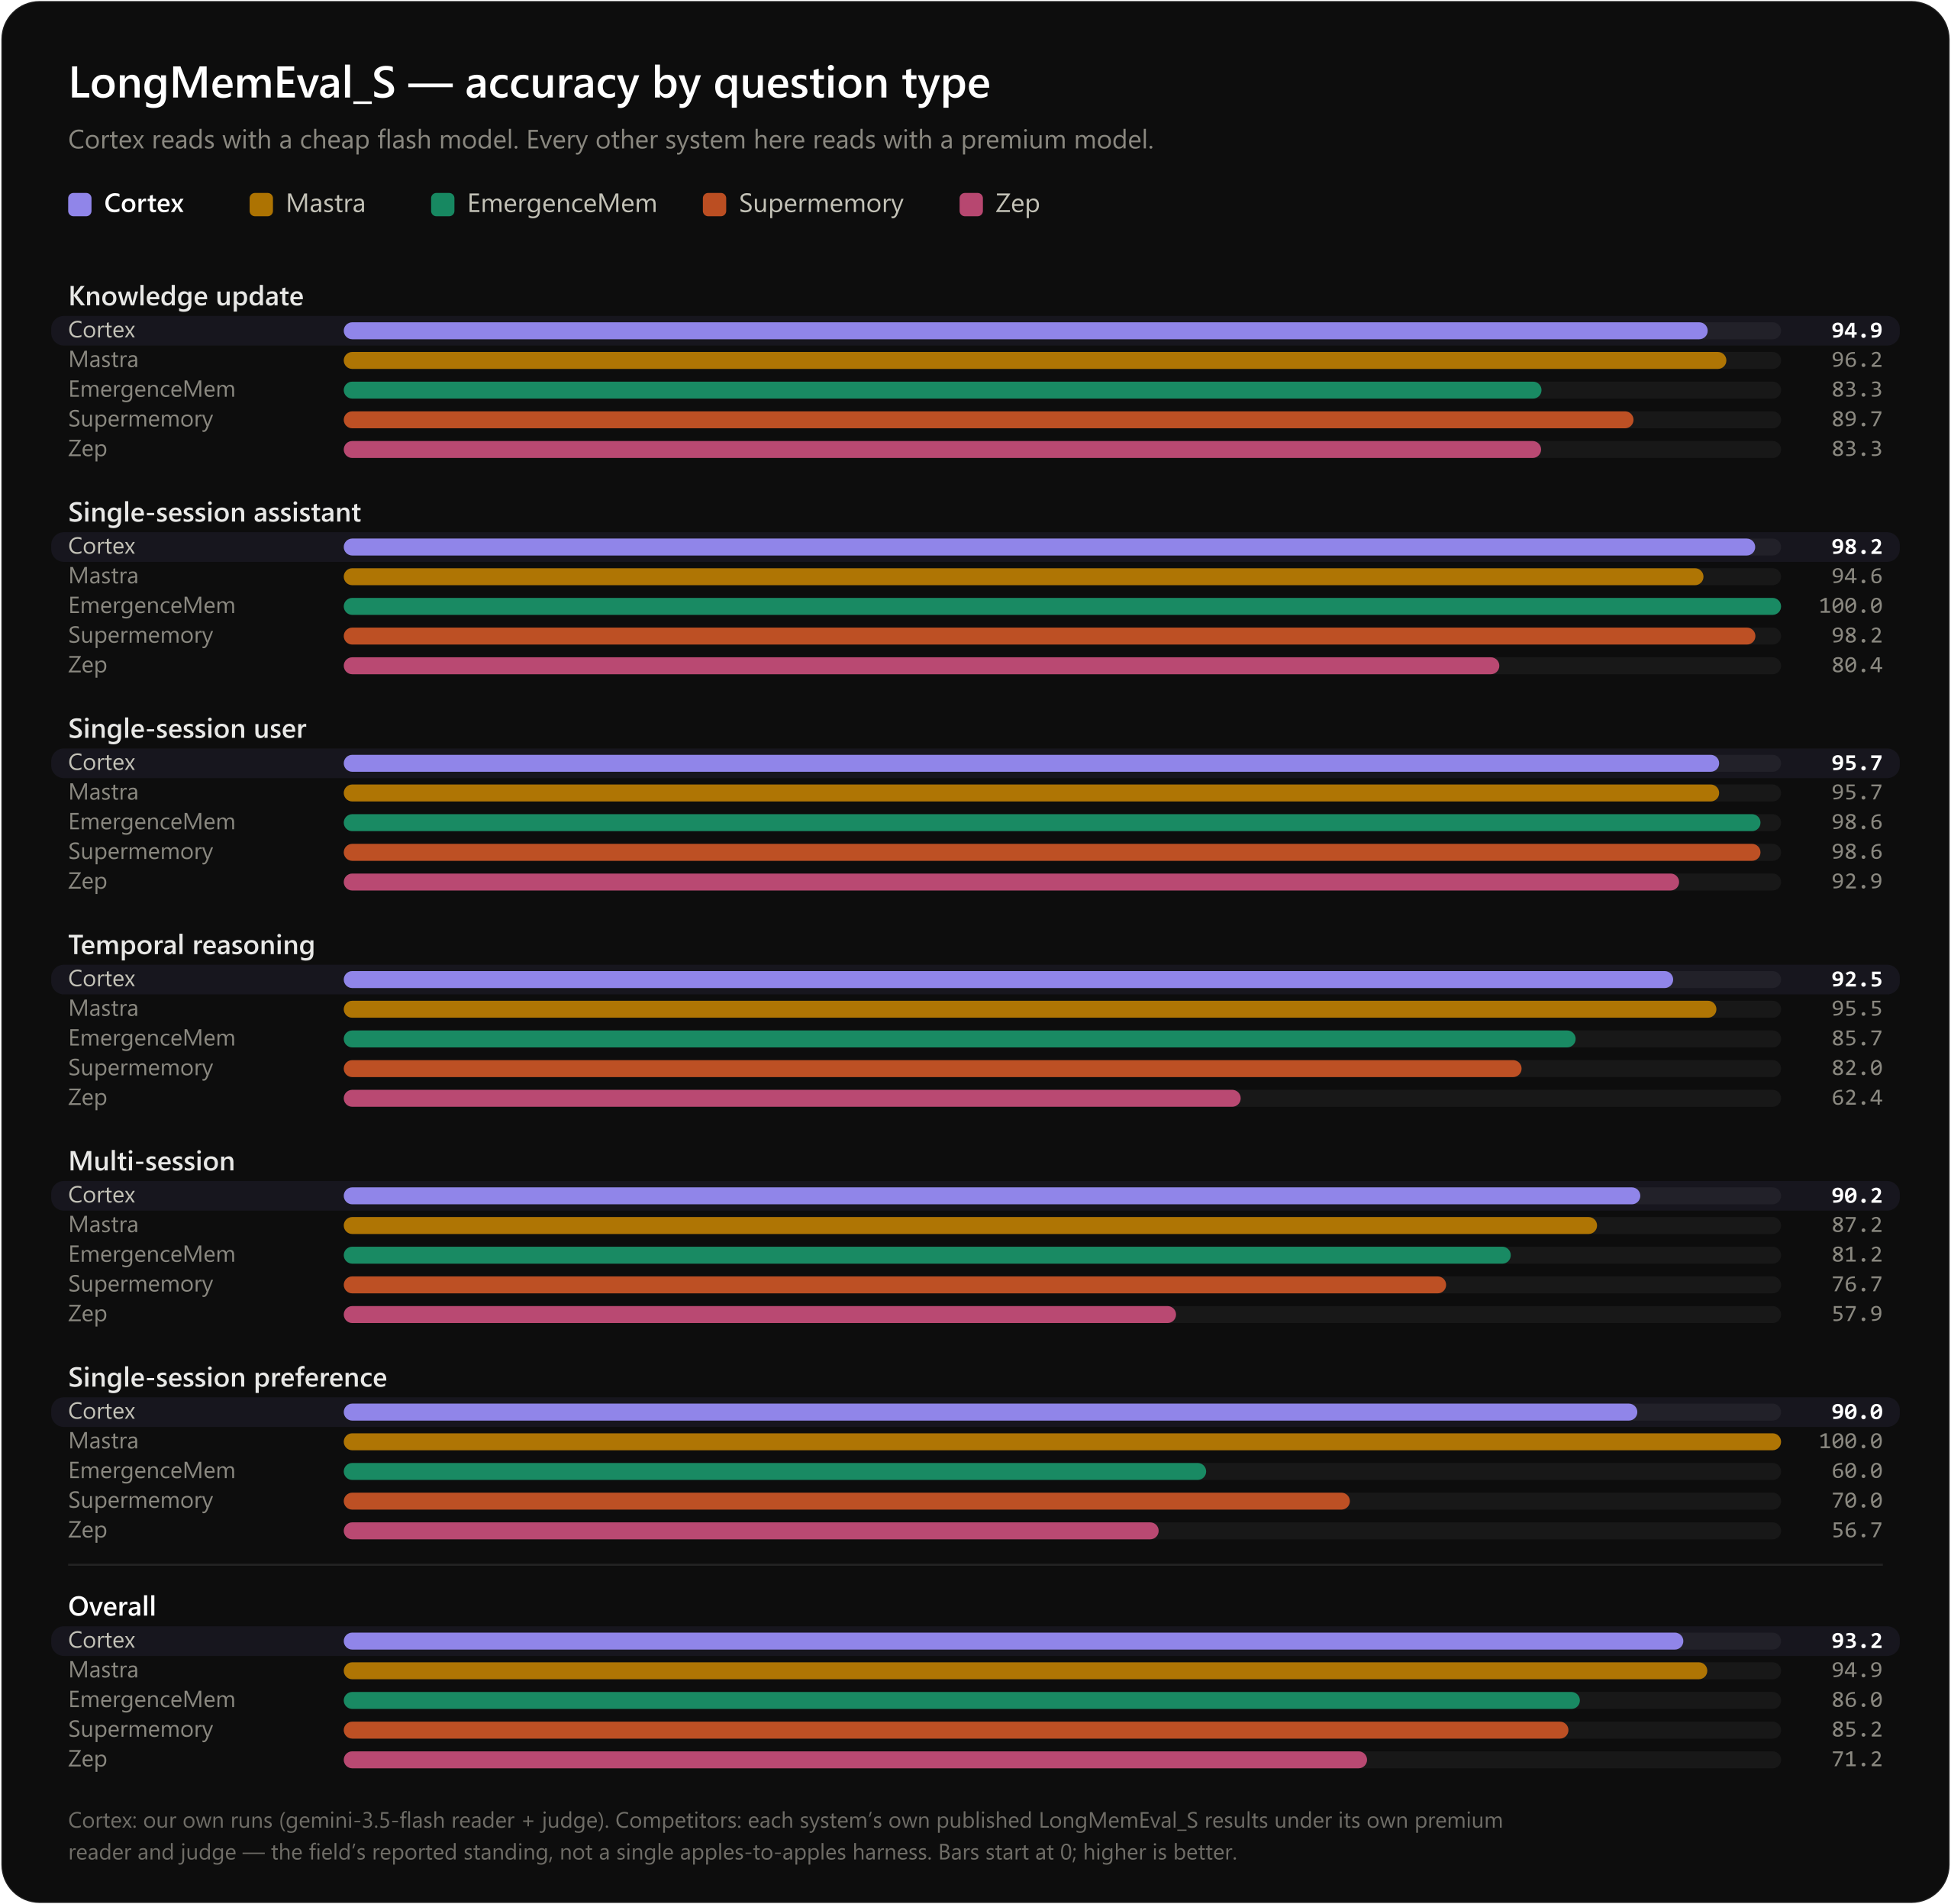
| Question type | **Cortex** `flash` | Mastra `premium` | EmergenceMem `premium` | Supermemory `premium` | Zep `premium` |
|---|:--:|:--:|:--:|:--:|:--:|
| Knowledge update | **94.9** | 96.2 | 83.3 | 89.7 | 83.3 |
| Single-session assistant | **98.2** | 94.6 | 100.0 | 98.2 | 80.4 |
| Single-session user | **95.7** | 95.7 | 98.6 | 98.6 | 92.9 |
| Temporal reasoning | **92.5** | 95.5 | 85.7 | 82.0 | 62.4 |
| Multi-session | **90.2** | 87.2 | 81.2 | 76.7 | 57.9 |
| Single-session preference | **90.0** | 100.0 | 60.0 | 70.0 | 56.7 |
| **Overall** | **93.2** | 94.9 | 86.0 | 85.2 | 71.2 |
<sub>Cortex's row is our own run (`gemini-3.5-flash` reader + judge). Competitor rows are each
system's own published LongMemEval_S results under its **own premium reader and judge** — the field's
reported standing, **not** a single apples-to-apples harness (the parody Supermemory "8/12-variant
ensemble" columns are excluded as satire; the real *Initial* column is used). Cortex's abstention
category (0.867) is omitted — competitors don't report it. Higher is better.</sub>
**LoCoMo 0.813** — per category: single-hop 0.864, multi-hop 0.695, temporal 0.857, open-domain
0.458, adversarial/abstention 0.836. This **beats the graph-memory systems** (Mem0 0.61–0.66, Zep
0.585–0.62) and is on par with the strong retrieval baseline EMem (0.78–0.84), behind only Cognis
(~0.925, Claude-Opus reader + reranker). Doubling retrieval depth (k=50→100) is what recovers
multi-hop (+10.6pt) — the LoCoMo frontier is retrieval depth, not reader capability.
### Reproduce
```bash
# LongMemEval_S — 0.932 headline (full 500):
python -m cortex_bench.run --system cortex-v0 --variant s --limit 500 \
--reader-model gemini-3.5-flash --top-k 50 --preference-mode --answer-first \
--max-output-tokens 8192 --judge gemini --judge-votes 3
# LongMemEval_S — cheap arm of the reader frontier (0.848), same retrieval, cheaper reader:
python -m cortex_bench.run --system cortex-v0 --variant s --limit 500 \
--reader-model gemini-2.5-flash --top-k 50 --preference-mode --answer-first \
--max-output-tokens 8192 --judge gemini --judge-votes 3
# LoCoMo — 0.813 (put locomo10.json in bench/data/ first):
python -m cortex_bench.run --system cortex-v0 --locomo --reader-model gemini-2.5-flash \
--top-k 100 --answer-first --max-output-tokens 8192 --judge gemini
```
Full methodology + per-type tables:
[`bench/results/PHASE3_authoritative.md`](https://github.com/fernsdavid25/cortex-protocol/blob/main/bench/results/PHASE3_authoritative.md)
(LongMemEval) and
[`bench/results/LOCOMO_results.md`](https://github.com/fernsdavid25/cortex-protocol/blob/main/bench/results/LOCOMO_results.md)
(LoCoMo); verified competitor leaderboard:
[`bench/results/leaderboard_research.md`](https://github.com/fernsdavid25/cortex-protocol/blob/main/bench/results/leaderboard_research.md).
## Features
| Capability | What it does | Status |
|---|---|---|
| **Hybrid retrieval** | Dense (Gemini embeddings) + Okapi BM25, fused with Reciprocal Rank Fusion (`k=60`, unweighted); each retriever is asked for a `4 × top_k` candidate pool so fusion can promote what both agree on. Deep top-k drives session-level recall@k ≈ 0.998. | **On** (all paths) |
| **Chain-of-Note reader** | The reader takes structured notes over the retrieved memories before answering, with **calibrated abstention** — it declines when no memory supports an answer instead of hallucinating. | **On** (benchmark path) |
| **Episodic memory + `recall_timeline`** | One cheap `gemini-2.5-flash-lite` call per `memorize` structures event_time / actor / location, powering the `recall_timeline` tool. **Write-time cost only — recall is byte-identical**, so the published recall cost is unchanged. | Opt-in (`CORTEX_EPISODIC=1`) |
| **Entity graph + `recall_about`** | At `memorize` time, entities and relationships are folded into the **same** cheap extraction call that does episodic. Builds an ego knowledge graph rooted at a synthetic `self` entity — typed nodes (person / place / org / project / thing) joined by labeled, directed relationships, each memory attached to the entity it's about — powering the `recall_about` tool. **Write-time cost only — recall stays byte-identical.** | Opt-in (`CORTEX_GRAPH=1`) |
| **Anti-saturation** | Write-time **dedup** (embedding-only, no LLM) bounds store growth; **contradiction soft-update** (one cheap arbiter call) writes a `supersessions` row so recall returns only the latest value. Implemented and unit-tested; **not yet measured at scale** — no saturation benchmark is published in this repo. | Engine-level, opt-in |
See [`docs/decades-scale.md`](https://github.com/fernsdavid25/cortex-protocol/blob/main/docs/decades-scale.md)
for the decades-scale retrieval analysis (self-host SQLite recall is O(n): measured ~95 ms @ 1k
memories → ~7.7 s p50 @ 50k).
## Architecture
Two paths, and the second one never calls an LLM.
```mermaid
flowchart TB
subgraph W["① SAVING — you tell an agent something worth keeping"]
direction LR
W1["memorize()"] --> W2["turn it into<br/>a searchable form"] --> W3["write it down"]
end
DB[("YOUR MEMORY<br/><i>one file, and it's yours</i>")]
subgraph R["② RECALLING — a different chat, days later — no AI model runs here"]
direction LR
R1["recall()"] --> R2["search it two ways —<br/>by meaning,<br/>and by exact words"] --> R3["hand back the<br/>memories that matter"]
end
A["YOUR AI reads them<br/>and answers you"]
W3 --> DB --> R2
R3 --> A
classDef step fill:#1b2a3d,stroke:#4b6a8a,color:#e6eefc
class W1,W2,W3,R1,R2,R3 step
style W fill:#0d1b2a,stroke:#3b82f6,color:#93c5fd
style R fill:#0c1f17,stroke:#22c55e,color:#86efac
style DB fill:#241f38,stroke:#a78bfa,color:#ddd6fe
style A fill:#141414,stroke:#9ca3af,color:#f3f4f6
```
**The invariant:** every enrichment layer runs at **write** time. Turning them on changes what is
*stored*, never what `recall` *does* — so the published per-recall cost holds no matter how many
layers you enable. `recall` is one embedding call plus local search, and returns raw memories.
**No LLM ever runs on the read path.**
### Inside `hybrid_retrieve`
Dense and lexical retrieval fail in different ways: embeddings miss rare exact tokens (names, IDs,
dates), BM25 misses paraphrase. Reciprocal Rank Fusion combines them **without score
normalization** — each list votes by *rank*, so a memory both retrievers like beats one only a
single retriever likes ([Cormack et al., 2009](https://dl.acm.org/doi/10.1145/1571941.1572114)).
```mermaid
flowchart LR
classDef q fill:#111,stroke:#666,color:#eee
classDef ret fill:#1a3d2e,stroke:#22c55e,color:#e6f7ee
classDef fuse fill:#2d2a3e,stroke:#a78bfa,color:#f0ecff
classDef out fill:#1e3a5f,stroke:#3b82f6,color:#e8f0fe
Q["query"]:::q
E["embed once"]:::q
D["<b>dense</b><br/>cosine over vectors<br/><i>catches paraphrase</i>"]:::ret
L["<b>lexical</b><br/>Okapi BM25<br/><i>catches exact tokens</i>"]:::ret
F{"<b>RRF</b><br/>k=60<br/>rank-vote fusion"}:::fuse
O["top-k memories"]:::out
Q --> E --> D
Q --> L
D -->|"4 × top_k pool"| F
L -->|"4 × top_k pool"| F
F --> O
```
## Teach your agent to use Cortex well
Connecting the server gives your agent the *tools*; the **Cortex agent skill** gives it the
*craft* — which tool answers which kind of question, how to phrase memories so the entity graph
and timeline actually build, and when to recall instead of re-asking you. One file, works in any
client (Claude Code skill, Cursor rules, or pasted instructions):
```bash
mkdir -p ~/.claude/skills/using-cortex-memory
curl -fsSL https://raw.githubusercontent.com/fernsdavid25/cortex-protocol/main/skills/using-cortex-memory/SKILL.md \
-o ~/.claude/skills/using-cortex-memory/SKILL.md
```
Canonical file: [`skills/using-cortex-memory/SKILL.md`](https://github.com/fernsdavid25/cortex-protocol/blob/main/skills/using-cortex-memory/SKILL.md)
· rendered: [docs → Agent skill](https://fernsdavid25.github.io/cortex-protocol/agent-skill/).
## Security & privacy
- **BYOK, no phone-home.** Your Gemini key is read from the environment and used only to call
Google's API. The local server has no backend and sends nothing anywhere else.
- **Your memory text is embedded by Google.** Each `memorize`/`recall` sends the content/query to
Google's embedding API *under your own key* — pick a key/project whose data-handling terms you're
comfortable with.
- **Local storage is a plain file.** Memories live unencrypted in `~/.cortex/memory.db`
(`CORTEX_DB_PATH`). Don't store secrets; protect the file like any local data, and set
`CORTEX_DB_PATH` only from trusted config (not from untrusted/agent input).
## Develop
```bash
uv run pytest # offline, deterministic test suite (FakeProvider — no live LLM calls)
uvx ruff check server # lint
```
See [`CHANGELOG.md`](https://github.com/fernsdavid25/cortex-protocol/blob/main/CHANGELOG.md) for
release notes and [`bench/README.md`](https://github.com/fernsdavid25/cortex-protocol/blob/main/bench/README.md)
for the benchmark harness.
## License
[Apache-2.0](https://github.com/fernsdavid25/cortex-protocol/blob/main/LICENSE)
MCP Config
Below is the configuration for this MCP Server. You can copy it directly to Cursor or other MCP clients.
mcp.json
Connection Info
You Might Also Like
No recommendations available